About Infere
We're building the infrastructure layer that makes AI accessible, affordable, and reliable for every development team on the planet.
Democratizing access to AI infrastructure
Infere is an intelligent AI routing and management platform. We connect your applications to every major AI provider through one OpenAI-compatible API - with automatic model selection, Git-native prompt management, AI evaluation, and enterprise-grade security, compliance, and analytics.
Engineering leaders are juggling fragmented AI vendors, opaque costs, and the risk of lock-in and production outages. Developers lack safe ways to evaluate prompt changes before they ship - and no one has a single view of what AI actually costs across teams.
Infere solves cost, reliability, and security together: an AI-powered model router that reduces spend, a Git-like prompt workflow with evaluation and observability, and enterprise controls that keep every request governed and auditable - across a global edge layer spanning 200+ locations.
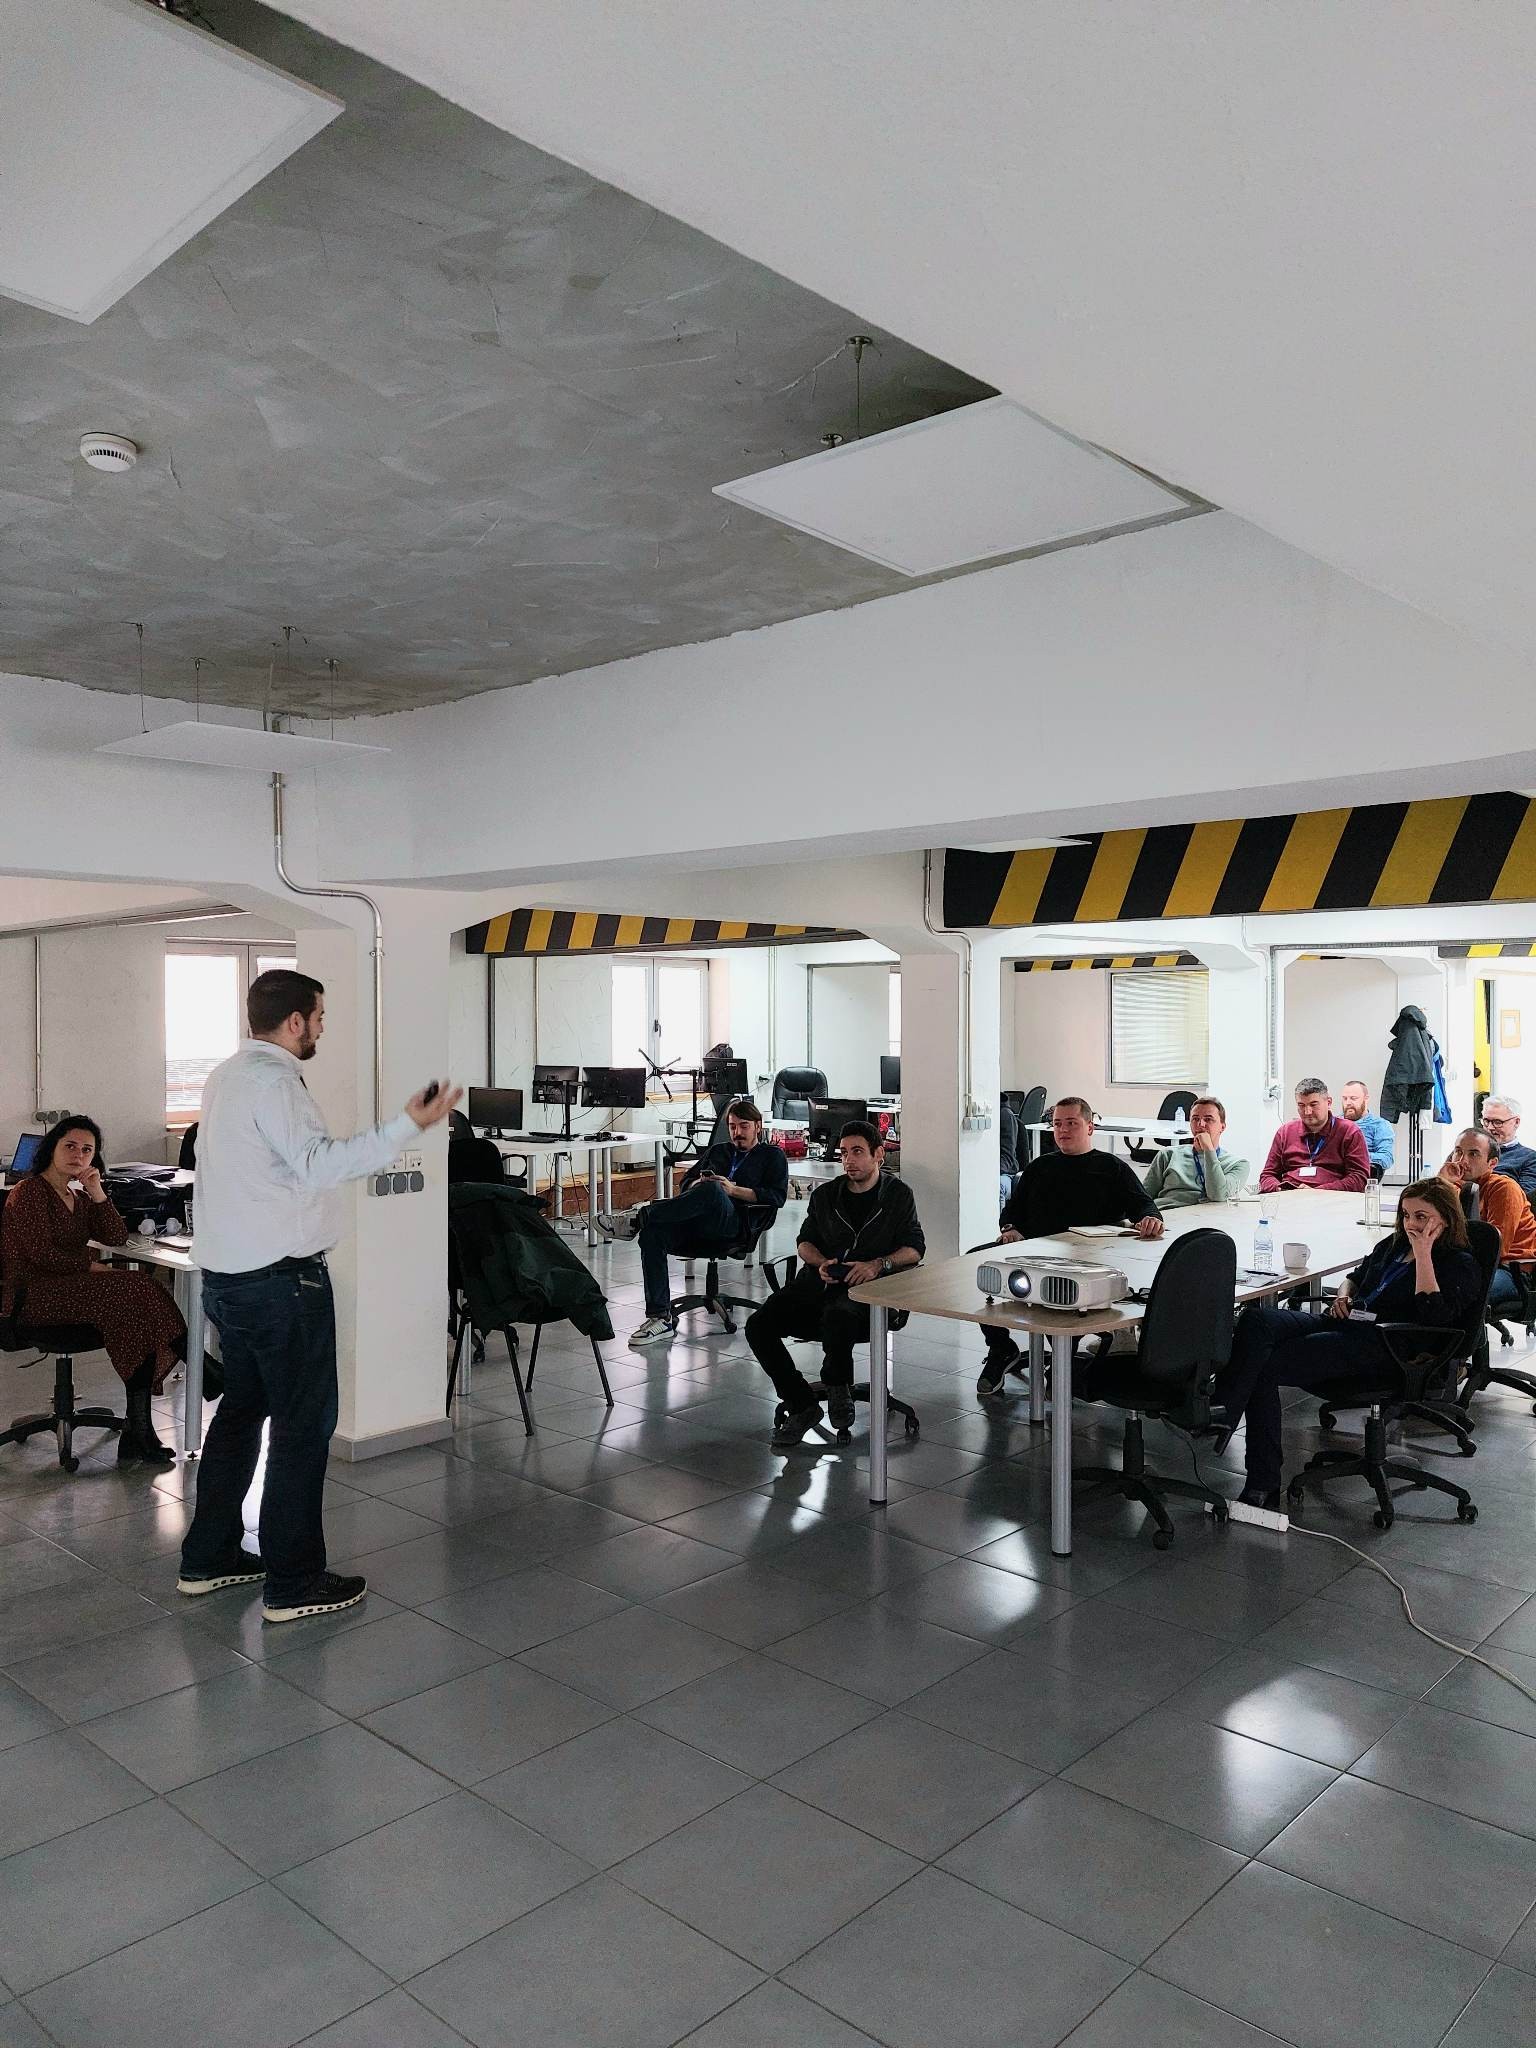
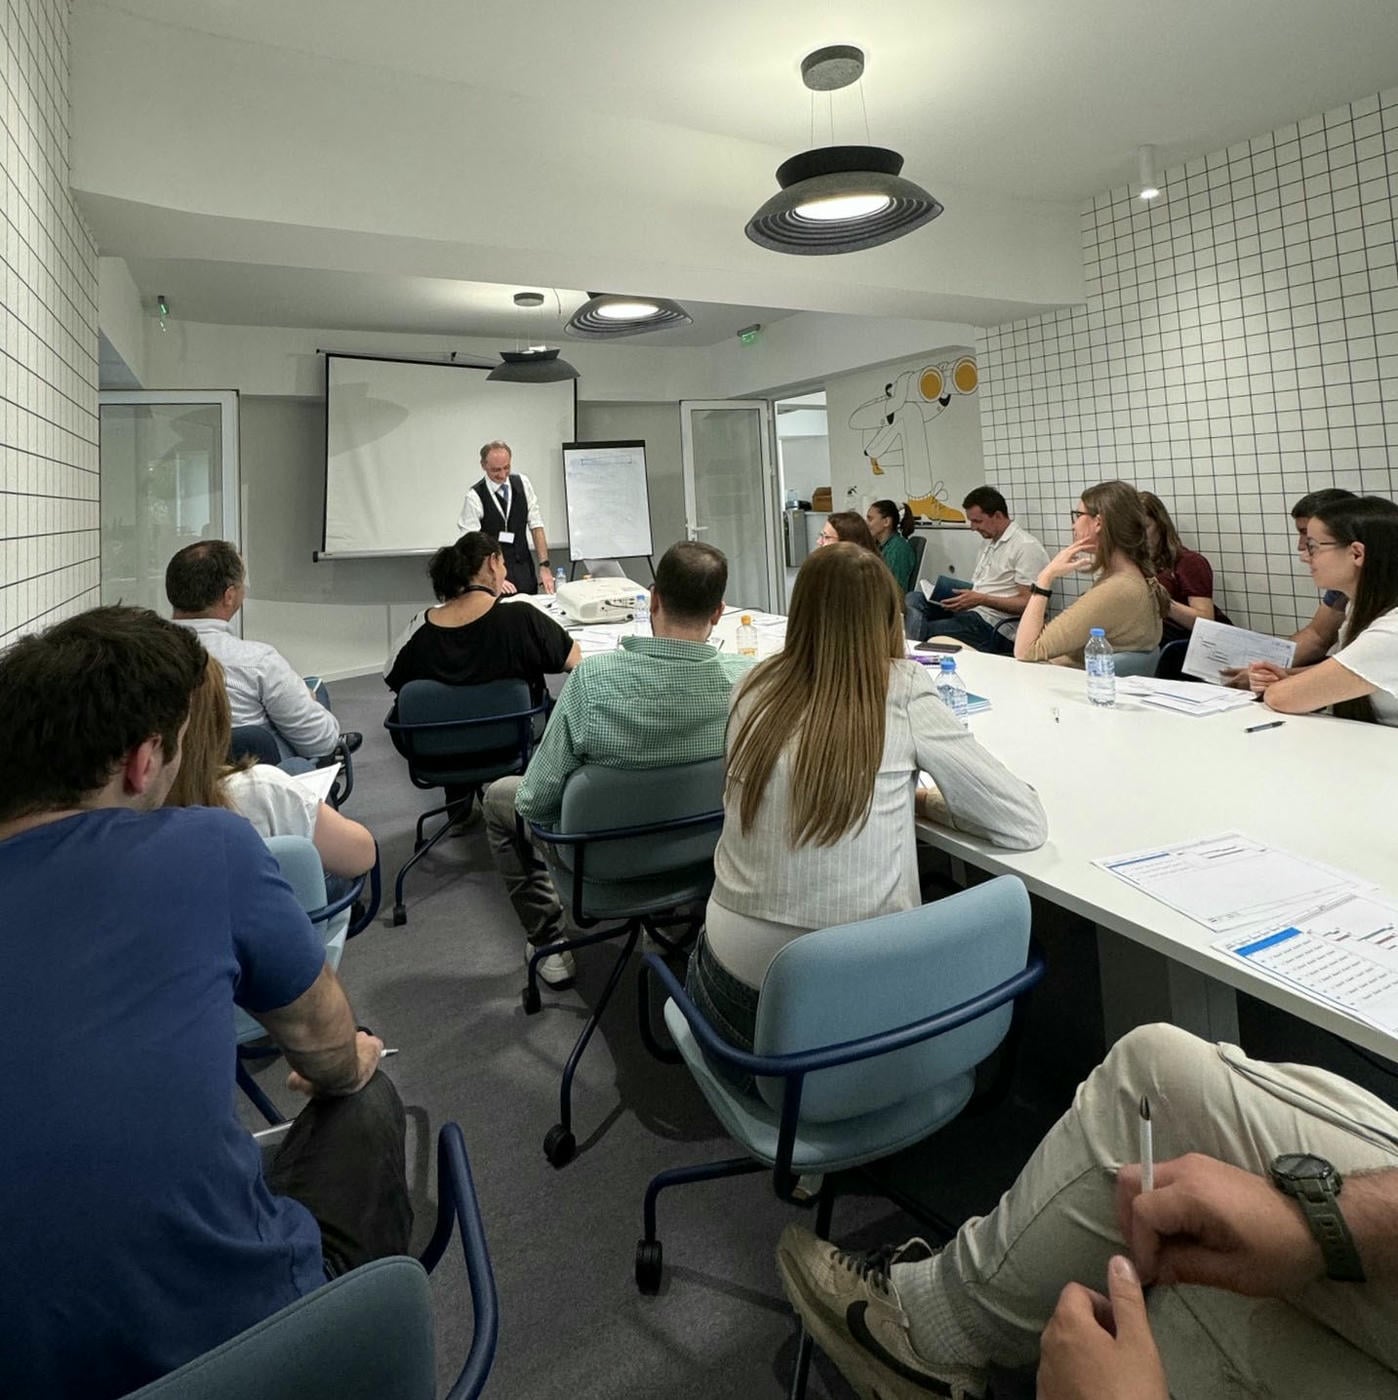
Meet the team
The people building the infrastructure layer for AI.
Built for teams shipping at scale
Enterprise Engineering Leaders
Gain central visibility into AI spend, enforce budgets per workspace, and stop shadow AI - without vendor lock-in or surprise cost overruns.
AI-Native Startups
Scale rapidly while managing AI costs with automatic routing, context compression, and one unified API - no in-house routing layer to build or maintain.
Developers
Treat prompts like code. Use your IDE and Git to modify, evaluate against production data, and deploy AI changes with absolute confidence.
An intelligent intermediary
Infere sits between your application and AI providers, adding intelligence, reliability, and control to every request - with the latest frontier models always within reach.
Git-Native Development
Write, version control, review, and test prompts exactly the same way you manage software infrastructure. No more hidden "magic strings".
Data-Driven Quality
Never ship a prompt blindly again. Evaluate changes against real production data, set quality baselines, and merge with confidence.
Unified Governance
One endpoint for all providers. Get complete observability into organization-wide spend, enforce per-request budgets, and monitor latency.
The principles behind our code
Transparency
No black boxes. We don't modify AI responses. We don't retain your data beyond what's needed for billing. Our routing decisions are explainable and auditable.
Intelligent Optimization
An AI-powered model router selects the best model for every request by complexity and capability - reducing AI spend while improving quality. Context compression trims tokens automatically.
Security
TLS 1.3 everywhere. AES-256 encryption at rest. SHA-256 hashed tokens. Role-based access control and full audit trails keep every request governed.
Reliability
Designed for 99.9% uptime across a global edge layer, with automatic multi-provider fallback and circuit breakers. A single provider outage should never take down your application.
Join the teams building with Infere
Start routing AI requests in minutes. Experience the difference intelligent infrastructure makes.